Last Thursday, a team of AI agents finished a proof of the Courtade–Kumar conjecture, an open problem in information theory since 2013. A second agent team formalized the Weil conjectures, André Weil’s 1940s program whose final proof by Pierre Deligne reshaped 20th-century mathematics, into about 1.8 million lines of machine-checked Lean. A third rewrote most of a production microkernel in Rust and made an AV1 decoder run 20–30% faster than the C++ original.
None of that happened because the models suddenly got smarter. It happened because of how the teams are arranged. And the arrangement is the part you can copy.
Google Research published the results from Antigravity’s /teamwork multi-agent harness on November 13, and the pattern running through every result is the same: generators working in parallel, each paired with independent falsifiers that cannot be argued with.
What the teams actually did
The headline math result is a full-generality proof of the Courtade–Kumar conjecture from 2013, done with researchers at CUHK, USC, and CMU, formalized in Lean 4 across roughly 50 million lines of code. The division of labor is the interesting part. Gemini’s first real contribution was finding counterexamples to a generalized version of the conjecture, which killed a tempting shortcut. The CUHK team then reduced the problem to a 14-variable optimization. From there, the agents built most of the analytical bounds and interval-arithmetic certificates, and extended the proof to unbalanced functions with no human input.
The LEAP framework pushed autonomy further. It produced an end-to-end, machine-checked formalization of the Weil conjectures (Deligne’s landmark from 1974) spanning about 1.8 million lines of Lean and 28,800 subagent invocations. Along the way the same machinery delivered first formalizations of Hilbert’s tenth problem over general integer rings (919,000 lines), the 3D Navier–Stokes finite-time blowup proof, the Birkhoff conjecture, and the Bochner–Riesz conjecture. One of those runs found a gap in a published informal proof and fixed it.
The engineering results deserve more attention than they got. A two-week campaign called Argon rewrote the remainder of the Zircon microkernel into roughly 800,000 lines of safe Rust that pass all tests and boot on arm64. The libgav1 AV1 decoder port ended up 20–30% faster than the original C++, and fully bit-exact, but only after the agents were given profiling tools. That last detail matters: the falsifier in that loop was a benchmark, and access to it changed the outcome.
The pattern: generators plus falsifiers
Strip away the domain and three moves remain, none of which need a supercomputer.
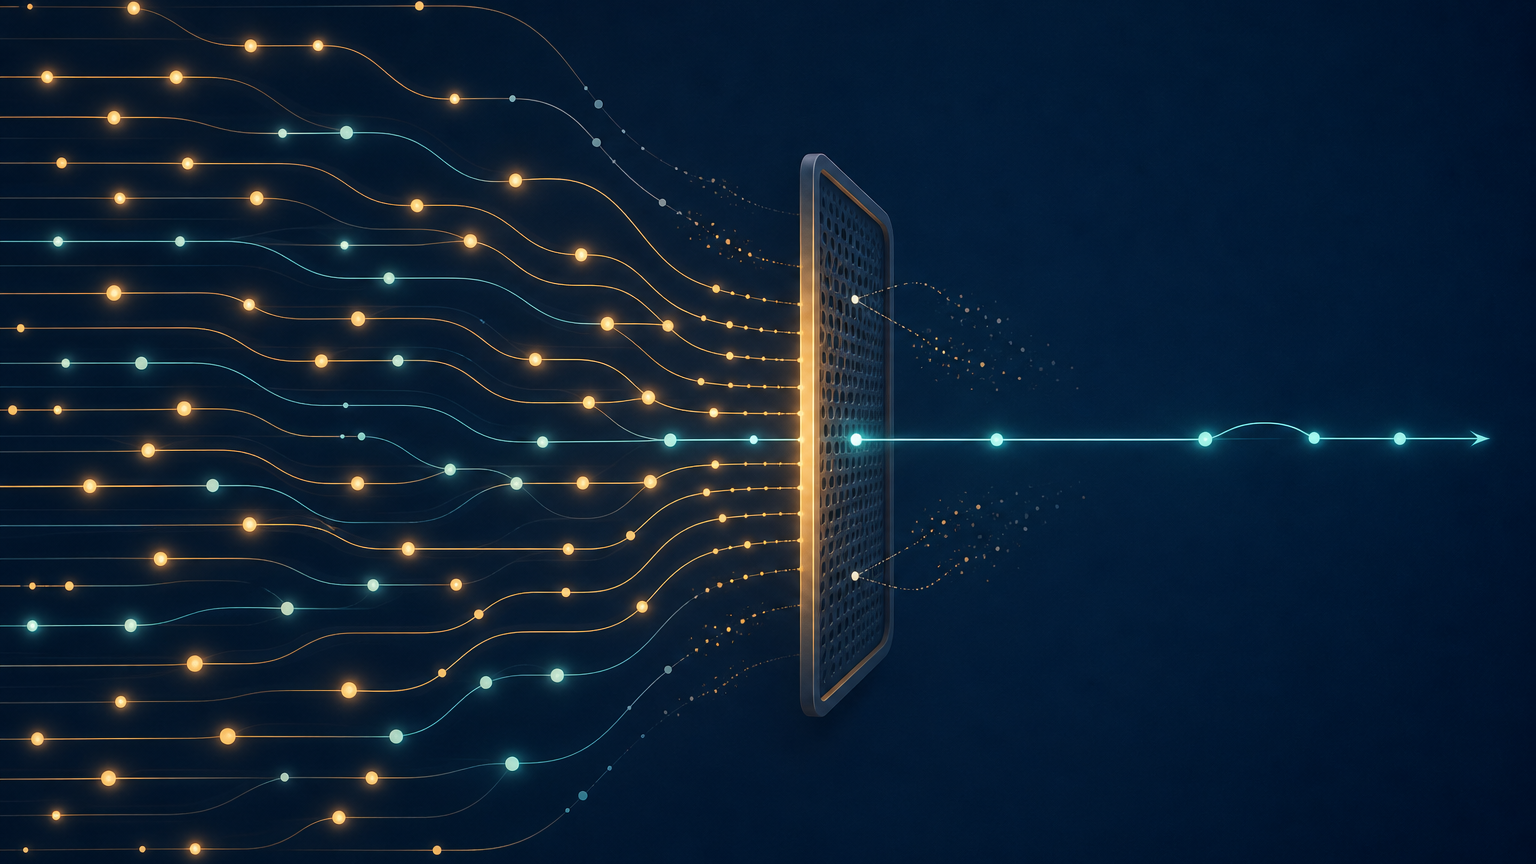
First, many generators run in parallel, exploring independently. Second, every generator faces a dedicated falsifier — a Lean checker, an unmodified test suite, a benchmark — that outputs a verdict, not an opinion. Third, context partitioning: each agent sees only the files and facts its own step needs, so nobody’s window fills with noise.
Why does this work so well? Verification is cheaper than generation. Checking a proof is mechanical; finding one is not. A model can hallucinate a plausible-looking lemma, but Lean cannot be persuaded. The falsifier needs no taste and no judgment, only the ability to say no — which is precisely the ability a generating model lacks when it grades its own work.
There’s a clean internal datapoint for this. A 30-agent workflow for NMR spectroscopy reached 95% top-1 exact match on molecule structure determination, about double what a single agent scored on the same task. Same pattern, different domain.
This is also my answer to anyone still arguing that single-agent chat is the end state of this technology. The gap between “sounds right” and “is right” is exactly where agent projects die in production, and the falsifier pattern is the most practical bridge across that gap anyone has demonstrated at scale.
Copying it without a fleet
You already own most of the machinery.
Your test suite is a falsifier. Instead of asking a model for one fix and hoping, run several attempts in parallel and let CI kill the losers. Model proposes, suite disposes. If your project has invariants, property-based tests sharpen the same blade.
If you work near specs or proofs, a real checker is the sharpest falsifier there is: Lean 4, Dafny, or TLA+ will machine-check claims that read as convincing prose. Machine-checked or it didn’t happen.
For performance work, require agents to beat a measured baseline rather than describe improvements. Google’s decoder got faster specifically when the agents could see the profiler. Give yours the profiler.
Context partitioning scales down too. Don’t dump the entire repository into one window. Give each worker the slice its step needs and let a coordinator merge results. It’s the same trick Google ran at 28,800 invocations, just smaller.
Caveats, from Google itself
Two honest disclaimers came with the announcement, and both are worth keeping. Until outside mathematicians confirm the formal statements match the original conjectures, the math results are Google’s own claims. And no cost figures were published for runs consuming tens of thousands of subagent invocations, so nobody outside can yet say what a proof costs in compute.
The adoption signal is real, though. Deep Review, built on the same infrastructure, was used by 578 of the submissions to STOC 2027 — more than a third of the conference — and over 30% of surveyed authors said it caught substantive proof bugs in their own work.
What to do now
- Pick one recurring task where output can be mechanically checked: tests, types, lint, benchmarks.
- Run multiple generator attempts in parallel, and let the verifier pick survivors. Track the pass rate.
- If the pass rate beats your single-shot rate, expand to the next task. If it doesn’t, your falsifier is too weak — fix that first.
The /teamwork features are rolling out to external Antigravity users over the coming weeks, and Google is giving 10,000 academic researchers six months of free top-tier access. The tools will arrive on their own schedule. The pattern doesn’t require waiting: a test suite plus three parallel attempts this afternoon is the whole idea, wearing smaller clothes.
Source: Google Research, “Advancing science and engineering with Antigravity’s teamwork feature,” November 13, 2026.