OpenAI says ChatGPT now reaches 1.2 billion people every week. Later this month, some of them will generate an image and find a product ad sitting next to the result.
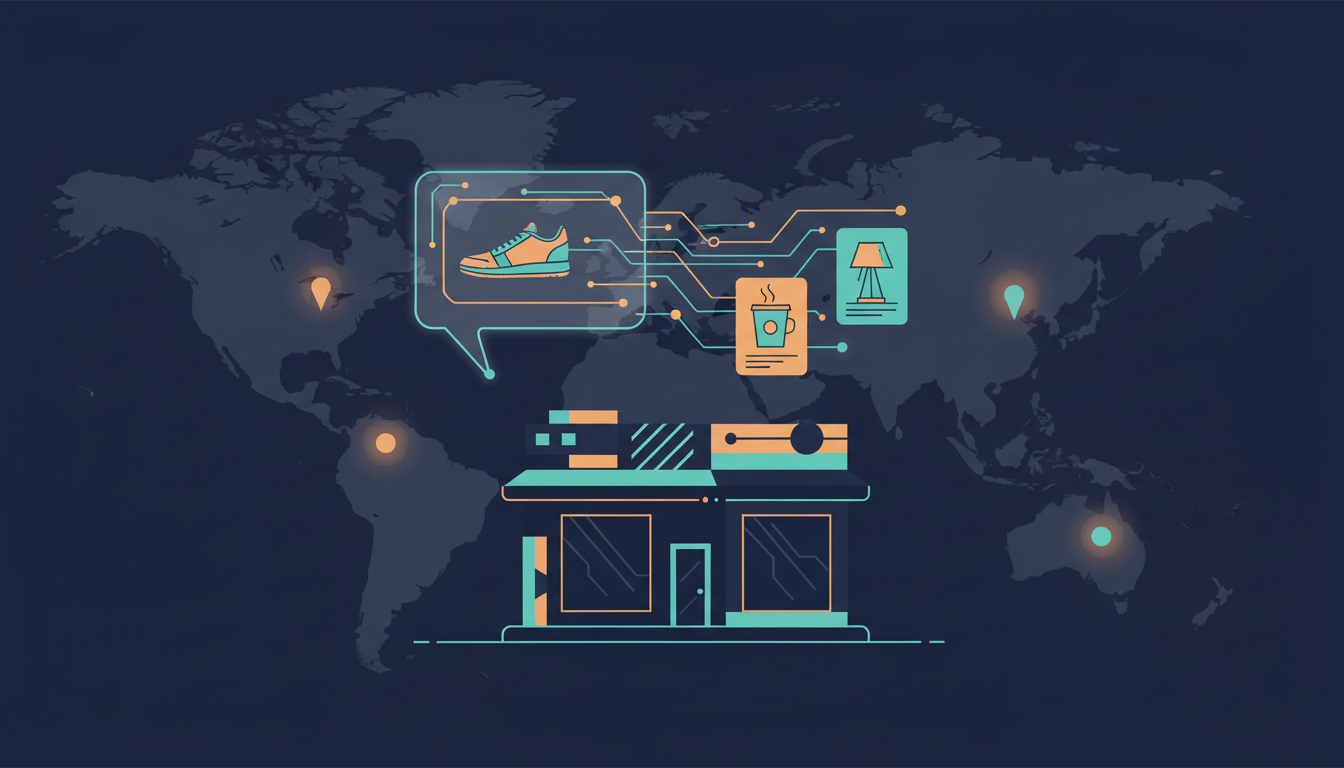
That’s the announcement: visual ads inside ChatGPT image generation, US testing with an initial advertiser group, product imagery shown alongside generated images. Clearly labeled, kept visually separate from whatever the model produced, and, in OpenAI’s words, with no influence on ChatGPT’s answers.
Here’s the part most coverage will skip. The same announcement shipped with a full measurement stack, including geo-based incrementality experiments run with Haus, Measured, and WorkMagic. Translation: nobody, including OpenAI, knows yet whether chat ads actually sell. The company is building the instruments to find out, and you should be too.
What actually shipped
The format is visual on purpose. Browsing inside a chat interface means looking at things: the jacket on a person, the desk in a room, the sofa in the living space. A text link next to a paragraph of prose does little work there. A product in use, in context, does more.
The initial test is US-only, later this month, with a select group of advertisers. Requests are open at ads.openai.com.
One claim deserves healthy skepticism: ads “never affect” ChatGPT’s answers. Maybe. But advertisers are about to pay for placement on a surface whose editorial layer and commercial layer are owned by the same company. Watch how that boundary gets policed over time, because regulators and brands both will.
The measurement stack is the real story
Three layers arrived simultaneously:
- Conversion integrations with Hightouch, Tealium, and LiveRamp, so purchase data can flow back in.
- Attribution support from AppsFlyer, Adjust, Triple Whale, Northbeam, Branch, Singular, Kochava, and others.
- Incrementality experiments with Haus, Measured, and WorkMagic, using geo-based testing.
That third layer matters most. OpenAI is not betting on clicks or view-through conversions to justify this surface. It is betting on causal lift measured by geography, the same standard mature performance teams already apply to Meta and TV.
Which sets the bar for you. If you can run a credible geo test, you’ll know within one budget cycle whether ChatGPT ads deserve more money. If you show up with last-click dashboards, you’ll spend the quarter arguing about credit instead of learning anything.
How to run the geo test
The method is old and boring, which is why it works.
Before launch:
- Pick 6 to 10 matched US markets. DMAs or states, split into test and holdout, with similar sales trends over the past year.
- Freeze the split before you see any results. Markets chosen after the fact are not a test.
- Stand up a baseline. Four weeks or more of pre-period data per market, so you can model what would have happened without the ads.
During the test:
- Spend enough to register. A trickle of impressions won’t move a market’s sales, and an underpowered test reads as “no effect” even when there is one.
- Keep everything else stable. No simultaneous promotions in test markets, or you’re measuring your discount, not your ads.
After:
- Compare actual sales in test markets against the model’s counterfactual. The gap is your incremental lift.
- Check for spillover. People search and buy across region lines, so border markets add noise. Exclude them or accept it.
If you already run geo lift studies on Meta with Haus or Measured, the workflow transfers almost directly. The planning is the hard part, not the tooling.
The organic side is about to get crowded
Paid placements and organic citations will compete for the same chat surface. Your generative engine optimization work, meaning getting products cited inside answers, decides whether an ad amplifies a presence you already have or substitutes for one you never built.
The teams to watch will treat chat as one surface: paid and organic answering to the same P&L, sharing the same product imagery, learning from the same queries. Everyone else will split it between two agencies and learn half as fast.
What to do this week
- Request access at ads.openai.com if US testing fits your market.
- Check whether your conversion data can actually reach Hightouch, Tealium, or LiveRamp. Data pipelines take longer than media plans.
- Choose your geo-test markets now and freeze them in writing.
- Prep in-context product imagery: in use, in scene, not pack shots on white.
- Write down the lift you expect before you spend. A number committed to in advance is the only honest benchmark.
The advantage here doesn’t go to the biggest budget. It goes to whoever can prove causal lift first, because that’s the team that gets the next budget. OpenAI handed you a surface with 1.2 billion weekly users and the tools to measure it honestly. Run the test.